Data Wrangling Lab
Estimated time needed: 45 minutes
In this lab, you will perform data wrangling tasks to prepare raw data for analysis. Data wrangling involves cleaning, transforming, and organizing data into a structured format suitable for analysis. This lab focuses on tasks like identifying inconsistencies, encoding categorical variables, and feature transformation.
Objectives
After completing this lab, you will be able to:
-
Identify and remove inconsistent data entries.
-
Encode categorical variables for analysis.
-
Handle missing values using multiple imputation strategies.
-
Apply feature scaling and transformation techniques.
Intsall the required libraries
!pip install pandas
!pip install matplotlib
Requirement already satisfied: pandas in /opt/conda/lib/python3.12/site-packages (3.0.0)
Requirement already satisfied: numpy>=1.26.0 in /opt/conda/lib/python3.12/site-packages (from pandas) (2.4.1)
Requirement already satisfied: python-dateutil>=2.8.2 in /opt/conda/lib/python3.12/site-packages (from pandas) (2.9.0.post0)
Requirement already satisfied: six>=1.5 in /opt/conda/lib/python3.12/site-packages (from python-dateutil>=2.8.2->pandas) (1.17.0)
Requirement already satisfied: matplotlib in /opt/conda/lib/python3.12/site-packages (3.10.8)
Requirement already satisfied: contourpy>=1.0.1 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (1.3.3)
Requirement already satisfied: cycler>=0.10 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (0.12.1)
Requirement already satisfied: fonttools>=4.22.0 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (4.61.1)
Requirement already satisfied: kiwisolver>=1.3.1 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (1.4.9)
Requirement already satisfied: numpy>=1.23 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (2.4.1)
Requirement already satisfied: packaging>=20.0 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (24.2)
Requirement already satisfied: pillow>=8 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (12.1.0)
Requirement already satisfied: pyparsing>=3 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (3.3.2)
Requirement already satisfied: python-dateutil>=2.7 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (2.9.0.post0)
Requirement already satisfied: six>=1.5 in /opt/conda/lib/python3.12/site-packages (from python-dateutil>=2.7->matplotlib) (1.17.0)
Tasks
Step 1: Import the necessary module.
1. Load the Dataset
1.1 Import necessary libraries and load the dataset.
Ensure the dataset is loaded correctly by displaying the first few rows.
# Import necessary libraries
import pandas as pd

# Load the Stack Overflow survey data
dataset_url = "https://cf-courses-data.s3.us.cloud-object-storage.appdomain.cloud/n01PQ9pSmiRX6520flujwQ/survey-data.csv"
df = pd.read_csv(dataset_url)

# Display the first few rows
print(df.head())
print('Initial dataframe:', df.shape)
   ResponseId                      MainBranch                 Age  \
0           1  I am a developer by profession  Under 18 years old
1           2  I am a developer by profession     35-44 years old
2           3  I am a developer by profession     45-54 years old
3           4           I am learning to code     18-24 years old
4           5  I am a developer by profession     18-24 years old

            Employment RemoteWork   Check  \
0  Employed, full-time     Remote  Apples
1  Employed, full-time     Remote  Apples
2  Employed, full-time     Remote  Apples
3   Student, full-time        NaN  Apples
4   Student, full-time        NaN  Apples

                                    CodingActivities  \
0                                              Hobby
1  Hobby;Contribute to open-source projects;Other...
2  Hobby;Contribute to open-source projects;Other...
3                                                NaN
4                                                NaN

                                             EdLevel  \
0                          Primary/elementary school
1       Bachelor’s degree (B.A., B.S., B.Eng., etc.)
2    Master’s degree (M.A., M.S., M.Eng., MBA, etc.)
3  Some college/university study without earning ...
4  Secondary school (e.g. American high school, G...

                                           LearnCode  \
0                             Books / Physical media
1  Books / Physical media;Colleague;On the job tr...
2  Books / Physical media;Colleague;On the job tr...
3  Other online resources (e.g., videos, blogs, f...
4  Other online resources (e.g., videos, blogs, f...

                                     LearnCodeOnline  ... JobSatPoints_6  \
0                                                NaN  ...            NaN
1  Technical documentation;Blogs;Books;Written Tu...  ...            0.0
2  Technical documentation;Blogs;Books;Written Tu...  ...            NaN
3  Stack Overflow;How-to videos;Interactive tutorial  ...            NaN
4  Technical documentation;Blogs;Written Tutorial...  ...            NaN

  JobSatPoints_7 JobSatPoints_8 JobSatPoints_9 JobSatPoints_10  \
0            NaN            NaN            NaN             NaN
1            0.0            0.0            0.0             0.0
2            NaN            NaN            NaN             NaN
3            NaN            NaN            NaN             NaN
4            NaN            NaN            NaN             NaN

  JobSatPoints_11           SurveyLength SurveyEase ConvertedCompYearly JobSat
0             NaN                    NaN        NaN                 NaN    NaN
1             0.0                    NaN        NaN                 NaN    NaN
2             NaN  Appropriate in length       Easy                 NaN    NaN
3             NaN               Too long       Easy                 NaN    NaN
4             NaN              Too short       Easy                 NaN    NaN

[5 rows x 114 columns]
Initial dataframe: (65437, 114)
2. Explore the Dataset
2.1 Summarize the dataset by displaying the column data types, counts, and missing values.
# Write your code here
#print(df.info(verbose=True, show_counts=True))
df_info = pd.DataFrame({
    'Data type': df.dtypes,
    'Counts': df.count(),
    'Missing values': df.isna().sum(),
    'Unique values': df.nunique()
}).reset_index(names='Column')

df_info = df_info.sort_values(by=['Column'])
print(df_info.to_string())
Column Data type Counts Missing values Unique values
66 AIAcc str 37302 28135 5
65 AIBen str 36894 28543 113
78 AIChallenges str 37531 27906 232
67 AIComplex str 37021 28416 5
77 AIEthics str 41548 23889 126
74 AINextLess integrated str 2355 63082 249
73 AINextMore integrated str 24428 41009 884
75 AINextMuch less integrated str 1148 64289 286
71 AINextMuch more integrated str 13438 51999 700
72 AINextNo change str 12498 52939 539
56 AISearchDevAdmired str 35543 29894 1488
54 AISearchDevHaveWorkedWith str 44453 20984 2663
55 AISearchDevWantToWorkWith str 36701 28736 2361
63 AISelect str 60907 4530 3
64 AISent str 45873 19564 6
76 AIThreat str 44689 20748 3
68 AIToolCurrently Using str 35072 30365 1310
69 AIToolInterested in Using str 30691 34746 1949
70 AIToolNot interested in Using str 24414 41023 1531
2 Age str 65437 0 8
17 BuildvsBuy str 43358 22079 3
16 BuyNewTool str 45181 20256 215
5 Check str 65437 0 1
6 CodingActivities str 54466 10971 118
21 CompTotal float64 33740 31697 3337
112 ConvertedCompYearly float64 23435 42002 6113
19 Country str 58930 6507 185
20 Currency str 46684 18753 142
27 DatabaseAdmired str 38557 26880 4051
25 DatabaseHaveWorkedWith str 50254 15183 9050
26 DatabaseWantToWorkWith str 42558 22879 8478
13 DevType str 59445 5992 34
7 EdLevel str 60784 4653 8
36 EmbeddedAdmired str 16733 48704 1053
34 EmbeddedHaveWorkedWith str 22214 43223 1630
35 EmbeddedWantToWorkWith str 17600 47837 1471
3 Employment str 65437 0 110
91 Frequency_1 str 28369 37068 5
92 Frequency_2 str 28364 37073 5
93 Frequency_3 str 27710 37727 5
96 Frustration str 28251 37186 954
80 ICorPM str 29801 35636 2
100 Industry str 28858 36579 15
113 JobSat float64 29126 36311 11
101 JobSatPoints_1 float64 29324 36113 91
108 JobSatPoints_10 float64 29450 35987 75
109 JobSatPoints_11 float64 29445 35992 79
102 JobSatPoints_4 float64 29393 36044 72
103 JobSatPoints_5 float64 29411 36026 78
104 JobSatPoints_6 float64 29450 35987 93
105 JobSatPoints_7 float64 29448 35989 91
106 JobSatPoints_8 float64 29456 35981 89
107 JobSatPoints_9 float64 29456 35981 85
82 Knowledge_1 str 28664 36773 5
83 Knowledge_2 str 28021 37416 5
84 Knowledge_3 str 28095 37342 5
85 Knowledge_4 str 28030 37407 5
86 Knowledge_5 str 27880 37557 5
87 Knowledge_6 str 27864 37573 5
88 Knowledge_7 str 27778 37659 5
89 Knowledge_8 str 27758 37679 5
90 Knowledge_9 str 27635 37802 5
24 LanguageAdmired str 50872 14565 12335
22 LanguageHaveWorkedWith str 59745 5692 23864
23 LanguageWantToWorkWith str 55752 9685 22769
8 LearnCode str 60488 4949 418
9 LearnCodeOnline str 49237 16200 10853
1 MainBranch str 65437 0 5
39 MiscTechAdmired str 29596 35841 4917
37 MiscTechHaveWorkedWith str 39443 25994 9288
38 MiscTechWantToWorkWith str 32964 32473 10263
45 NEWCollabToolsAdmired str 50711 14726 7545
43 NEWCollabToolsHaveWorkedWith str 57592 7845 14168
44 NEWCollabToolsWantToWorkWith str 52087 13350 9751
57 NEWSOSites str 60286 5151 32
50 OfficeStackAsyncAdmired str 37204 28233 2661
48 OfficeStackAsyncHaveWorkedWith str 48093 17344 6014
49 OfficeStackAsyncWantToWorkWith str 38966 26471 3801
53 OfficeStackSyncAdmired str 44712 20725 2555
51 OfficeStackSyncHaveWorkedWith str 55545 9892 5049
52 OfficeStackSyncWantToWorkWith str 46711 18726 3205
46 OpSysPersonal use str 58174 7263 2488
47 OpSysProfessional use str 52973 12464 2032
14 OrgSize str 47480 17957 10
30 PlatformAdmired str 31377 34060 2556
28 PlatformHaveWorkedWith str 42366 23071 5467
29 PlatformWantToWorkWith str 34532 30905 4784
98 ProfessionalCloud str 28491 36946 3
99 ProfessionalQuestion str 28807 36630 9
97 ProfessionalTech str 27764 37673 514
15 PurchaseInfluence str 47406 18031 3
4 RemoteWork str 54806 10631 3
0 ResponseId int64 65437 0 65437
59 SOAccount str 59560 5877 3
62 SOComm str 59163 6274 6
61 SOHow str 58962 6475 111
60 SOPartFreq str 45237 20200 6
58 SOVisitFreq str 59536 5901 5
111 SurveyEase str 56238 9199 3
110 SurveyLength str 56182 9255 3
79 TBranch str 44477 20960 2
10 TechDoc str 40897 24540 113
18 TechEndorse str 43668 21769 386
95 TimeAnswering str 28844 36593 5
94 TimeSearching str 28911 36526 5
42 ToolsTechAdmired str 43997 21440 11804
40 ToolsTechHaveWorkedWith str 52482 12955 19883
41 ToolsTechWantToWorkWith str 46084 19353 16549
33 WebframeAdmired str 34943 30494 5460
31 WebframeHaveWorkedWith str 45161 20276 12235
32 WebframeWantToWorkWith str 38535 26902 11654
81 WorkExp float64 29658 35779 51
11 YearsCode str 59869 5568 52
12 YearsCodePro str 51610 13827 52
2.2 Generate basic statistics for numerical columns.
# Write your code here
print(df.describe())
         ResponseId      CompTotal       WorkExp  JobSatPoints_1  \
count  65437.000000   3.374000e+04  29658.000000    29324.000000
mean   32719.000000  2.963841e+145     11.466957       18.581094
std    18890.179119  5.444117e+147      9.168709       25.966221
min        1.000000   0.000000e+00      0.000000        0.000000
25%    16360.000000   6.000000e+04      4.000000        0.000000
50%    32719.000000   1.100000e+05      9.000000       10.000000
75%    49078.000000   2.500000e+05     16.000000       22.000000
max    65437.000000  1.000000e+150     50.000000      100.000000

       JobSatPoints_4  JobSatPoints_5  JobSatPoints_6  JobSatPoints_7  \
count    29393.000000    29411.000000    29450.000000     29448.00000
mean         7.522140       10.060857       24.343232        22.96522
std         18.422661       21.833836       27.089360        27.01774
min          0.000000        0.000000        0.000000         0.00000
25%          0.000000        0.000000        0.000000         0.00000
50%          0.000000        0.000000       20.000000        15.00000
75%          5.000000       10.000000       30.000000        30.00000
max        100.000000      100.000000      100.000000       100.00000

       JobSatPoints_8  JobSatPoints_9  JobSatPoints_10  JobSatPoints_11  \
count    29456.000000    29456.000000     29450.000000     29445.000000
mean        20.278165       16.169432        10.955713         9.953948
std         26.108110       24.845032        22.906263        21.775652
min          0.000000        0.000000         0.000000         0.000000
25%          0.000000        0.000000         0.000000         0.000000
50%         10.000000        5.000000         0.000000         0.000000
75%         25.000000       20.000000        10.000000        10.000000
max        100.000000      100.000000       100.000000       100.000000

       ConvertedCompYearly        JobSat
count         2.343500e+04  29126.000000
mean          8.615529e+04      6.935041
std           1.867570e+05      2.088259
min           1.000000e+00      0.000000
25%           3.271200e+04      6.000000
50%           6.500000e+04      7.000000
75%           1.079715e+05      8.000000
max           1.625660e+07     10.000000
3. Identifying and Removing Inconsistencies
3.1 Identify inconsistent or irrelevant entries in specific columns (e.g., Country).
# Write your code here
print(sorted(df.Country.fillna('Unknown').unique()))  # There are missing values
['Afghanistan', 'Albania', 'Algeria', 'Andorra', 'Angola', 'Antigua and Barbuda', 'Argentina', 'Armenia', 'Australia', 'Austria', 'Azerbaijan', 'Bahamas', 'Bahrain', 'Bangladesh', 'Barbados', 'Belarus', 'Belgium', 'Belize', 'Benin', 'Bhutan', 'Bolivia', 'Bosnia and Herzegovina', 'Botswana', 'Brazil', 'Brunei Darussalam', 'Bulgaria', 'Burkina Faso', 'Burundi', 'Cambodia', 'Cameroon', 'Canada', 'Cape Verde', 'Central African Republic', 'Chad', 'Chile', 'China', 'Colombia', 'Congo, Republic of the...', 'Costa Rica', 'Croatia', 'Cuba', 'Cyprus', 'Czech Republic', "Côte d'Ivoire", "Democratic People's Republic of Korea", 'Democratic Republic of the Congo', 'Denmark', 'Djibouti', 'Dominica', 'Dominican Republic', 'Ecuador', 'Egypt', 'El Salvador', 'Equatorial Guinea', 'Estonia', 'Ethiopia', 'Fiji', 'Finland', 'France', 'Gabon', 'Georgia', 'Germany', 'Ghana', 'Greece', 'Guatemala', 'Guinea', 'Guinea-Bissau', 'Guyana', 'Haiti', 'Honduras', 'Hong Kong (S.A.R.)', 'Hungary', 'Iceland', 'India', 'Indonesia', 'Iran, Islamic Republic of...', 'Iraq', 'Ireland', 'Isle of Man', 'Israel', 'Italy', 'Jamaica', 'Japan', 'Jordan', 'Kazakhstan', 'Kenya', 'Kosovo', 'Kuwait', 'Kyrgyzstan', "Lao People's Democratic Republic", 'Latvia', 'Lebanon', 'Lesotho', 'Liberia', 'Libyan Arab Jamahiriya', 'Liechtenstein', 'Lithuania', 'Luxembourg', 'Madagascar', 'Malawi', 'Malaysia', 'Maldives', 'Mali', 'Malta', 'Mauritania', 'Mauritius', 'Mexico', 'Micronesia, Federated States of...', 'Monaco', 'Mongolia', 'Montenegro', 'Morocco', 'Mozambique', 'Myanmar', 'Namibia', 'Nauru', 'Nepal', 'Netherlands', 'New Zealand', 'Nicaragua', 'Niger', 'Nigeria', 'Nomadic', 'North Korea', 'Norway', 'Oman', 'Pakistan', 'Palestine', 'Panama', 'Papua New Guinea', 'Paraguay', 'Peru', 'Philippines', 'Poland', 'Portugal', 'Qatar', 'Republic of Korea', 'Republic of Moldova', 'Republic of North Macedonia', 'Romania', 'Russian Federation', 'Rwanda', 'Saint Kitts and Nevis', 'Samoa', 'San Marino', 'Saudi Arabia', 'Senegal', 'Serbia', 'Sierra Leone', 'Singapore', 'Slovakia', 'Slovenia', 'Solomon Islands', 'Somalia', 'South Africa', 'South Korea', 'Spain', 'Sri Lanka', 'Sudan', 'Suriname', 'Swaziland', 'Sweden', 'Switzerland', 'Syrian Arab Republic', 'Taiwan', 'Tajikistan', 'Thailand', 'Togo', 'Trinidad and Tobago', 'Tunisia', 'Turkey', 'Turkmenistan', 'Uganda', 'Ukraine', 'United Arab Emirates', 'United Kingdom of Great Britain and Northern Ireland', 'United Republic of Tanzania', 'United States of America', 'Unknown', 'Uruguay', 'Uzbekistan', 'Venezuela, Bolivarian Republic of...', 'Viet Nam', 'Yemen', 'Zambia', 'Zimbabwe']
print(sorted(df.EdLevel.fillna('Unknown').unique())) # There are missing values
['Associate degree (A.A., A.S., etc.)', 'Bachelor’s degree (B.A., B.S., B.Eng., etc.)', 'Master’s degree (M.A., M.S., M.Eng., MBA, etc.)', 'Primary/elementary school', 'Professional degree (JD, MD, Ph.D, Ed.D, etc.)', 'Secondary school (e.g. American high school, German Realschule or Gymnasium, etc.)', 'Some college/university study without earning a degree', 'Something else', 'Unknown']
3.2 Standardize entries in columns like Country or EdLevel by mapping inconsistent values to a consistent format.
## Write your code here
df_i = df.copy()
df_i.Country = df_i.Country.fillna('Unknown')
df_i.EdLevel = df_i.EdLevel.fillna('Unknown')
print(df_i.Country.isna().sum(), df_i.EdLevel.isna().sum())
0 0
4. Encoding Categorical Variables
4.1 Encode the Employment column using one-hot encoding.
## Write your code here
## One Hot Encoding is a method for converting categorical variables into a binary format.
#print(sorted(df_i.Employment.unique()))
#employment_dummies = pd.get_dummies(df_i['Employment'])
cat = set()
empl = df_i.Employment.unique()
for el in empl:
    if ';' in el:
        cat = cat | set(el.split(';'))
    else:
        cat.add(el)
cat = sorted(cat)
print(cat, len(cat))  # Columns that should be added to the dataframe
['Employed, full-time', 'Employed, part-time', 'I prefer not to say', 'Independent contractor, freelancer, or self-employed', 'Not employed, and not looking for work', 'Not employed, but looking for work', 'Retired', 'Student, full-time', 'Student, part-time'] 9
df_ie = df_i.copy()
dummies = df_ie['Employment'].str.get_dummies(sep=';').astype(bool)
df_ie = pd.concat([df_ie, dummies], axis=1)
print(df_ie[['Employment', *cat]].head())
print(df_ie.shape)
            Employment  Employed, full-time  Employed, part-time  \
0  Employed, full-time                 True                False
1  Employed, full-time                 True                False
2  Employed, full-time                 True                False
3   Student, full-time                False                False
4   Student, full-time                False                False

   I prefer not to say  Independent contractor, freelancer, or self-employed  \
0                False                                              False
1                False                                              False
2                False                                              False
3                False                                              False
4                False                                              False

   Not employed, and not looking for work  Not employed, but looking for work  \
0                                   False                               False
1                                   False                               False
2                                   False                               False
3                                   False                               False
4                                   False                               False

   Retired  Student, full-time  Student, part-time
0    False               False               False
1    False               False               False
2    False               False               False
3    False                True               False
4    False                True               False
(65437, 123)
5. Handling Missing Values
5.1 Identify columns with the highest number of missing values.
## Write your code here
frnan = df_ie.isna().mean().sort_values(ascending=False).round(decimals=4)
print('Fraction of missing values in each column')
print(frnan.head())
print('RemoteWork:', frnan.RemoteWork)
print('ConvertedCompYearly:', frnan.ConvertedCompYearly)
Fraction of missing values in each column
AINextMuch less integrated    0.9825
AINextLess integrated         0.9640
AINextNo change               0.8090
AINextMuch more integrated    0.7946
EmbeddedAdmired               0.7443
dtype: float64
RemoteWork: 0.1625
ConvertedCompYearly: 0.6419
5.2 Impute missing values in numerical columns (e.g., `ConvertedCompYearly`) with the mean or median.
import matplotlib.pyplot as plt
## Write your code here
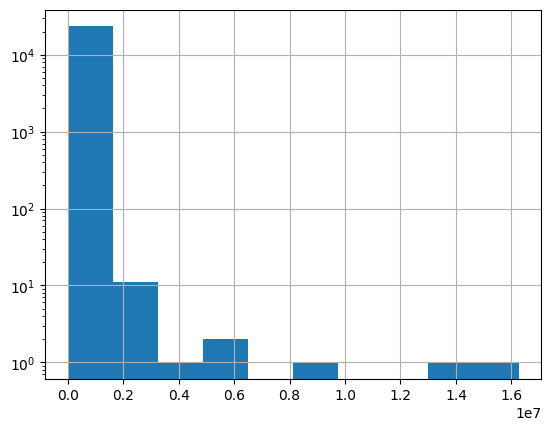
print('Number of unique values:', df_ie.ConvertedCompYearly.nunique(dropna=False))
df_ie.ConvertedCompYearly.hist(log=True)
plt.show()
Number of unique values: 6114
## Write your code here
# The data in the ConvertedCompYearly column has 64% outliers and it is skewed.
# Hence, it is better to use a median value.
MedianValue = df_ie['ConvertedCompYearly'].median()
df_ie['ConvertedCompYearly'] = df_ie['ConvertedCompYearly'].fillna(MedianValue)
print(df_ie['ConvertedCompYearly'].describe().astype(int))
count       65437
mean        72576
std        112220
min             1
25%         65000
50%         65000
75%         65000
max      16256603
Name: ConvertedCompYearly, dtype: int64
5.3 Impute missing values in categorical columns (e.g., `RemoteWork`) with the most frequent value.
## Write your code here
print(df_ie.RemoteWork.describe())
count                                    54806
unique                                       3
top       Hybrid (some remote, some in-person)
freq                                     23015
Name: RemoteWork, dtype: object
common_RemoteWork = df_ie.RemoteWork.value_counts().idxmax()
df_ie.RemoteWork = df_ie.RemoteWork.fillna(common_RemoteWork)
print(df_ie['RemoteWork'].describe())
count                                    65437
unique                                       3
top       Hybrid (some remote, some in-person)
freq                                     33646
Name: RemoteWork, dtype: object
6. Feature Scaling and Transformation
6.1 Apply Min-Max Scaling to normalize the `ConvertedCompYearly` column.
## Write your code here
df_ie['ConvertedCompYearly_MinMax'] = (df_ie['ConvertedCompYearly'] - df_ie['ConvertedCompYearly'].min()) / (df_ie['ConvertedCompYearly'].max() - df_ie['ConvertedCompYearly'].min())
print(df_ie['ConvertedCompYearly_MinMax'].describe())
count    65437.000000
mean         0.004464
std          0.006903
min          0.000000
25%          0.003998
50%          0.003998
75%          0.003998
max          1.000000
Name: ConvertedCompYearly_MinMax, dtype: float64
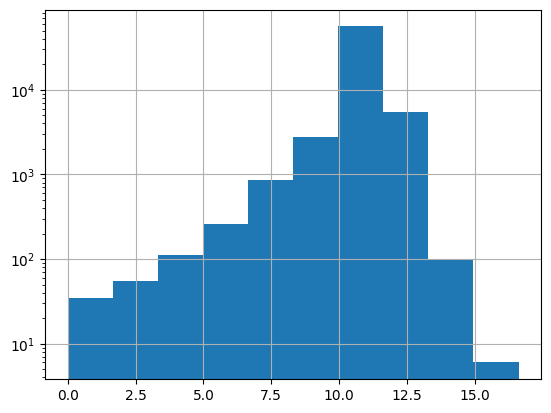
6.2 Log-transform the ConvertedCompYearly column to reduce skewness.
## Write your code here
import numpy as np
df_ie['ConvertedCompYearly_Log'] = np.log(df_ie['ConvertedCompYearly'])
df_ie.ConvertedCompYearly_Log.hist(log=True)
plt.show()
7. Feature Engineering
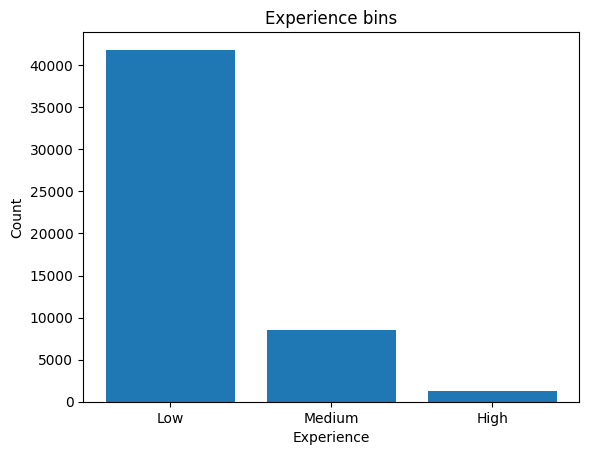
7.1 Create a new column `ExperienceLevel` based on the `YearsCodePro` column:
## Write your code here
print(sorted(df_ie.YearsCodePro.fillna('Unknown').unique()))
['1', '10', '11', '12', '13', '14', '15', '16', '17', '18', '19', '2', '20', '21', '22', '23', '24', '25', '26', '27', '28', '29', '3', '30', '31', '32', '33', '34', '35', '36', '37', '38', '39', '4', '40', '41', '42', '43', '44', '45', '46', '47', '48', '49', '5', '50', '6', '7', '8', '9', 'Less than 1 year', 'More than 50 years', 'Unknown']
df_fe = pd.DataFrame(df_ie.YearsCodePro)
df_fe = df_fe.dropna()
df_fe = df_fe.replace({'Less than 1 year': 0, 'More than 50 years': 51}).astype(int)

bins = np.linspace(min(df_fe.YearsCodePro), max(df_fe.YearsCodePro), 4)
group_names = ['Low', 'Medium', 'High']
df_fe['ExperienceLevel'] = pd.cut(df_fe.YearsCodePro, bins, labels=group_names, include_lowest=True )

df_iefe = pd.concat([df_ie, df_fe.ExperienceLevel], axis=1)
print(df_iefe.shape)
print(df_iefe.head())
(65437, 126)
   ResponseId                      MainBranch                 Age  \
0           1  I am a developer by profession  Under 18 years old
1           2  I am a developer by profession     35-44 years old
2           3  I am a developer by profession     45-54 years old
3           4           I am learning to code     18-24 years old
4           5  I am a developer by profession     18-24 years old

            Employment                            RemoteWork   Check  \
0  Employed, full-time                                Remote  Apples
1  Employed, full-time                                Remote  Apples
2  Employed, full-time                                Remote  Apples
3   Student, full-time  Hybrid (some remote, some in-person)  Apples
4   Student, full-time  Hybrid (some remote, some in-person)  Apples

                                    CodingActivities  \
0                                              Hobby
1  Hobby;Contribute to open-source projects;Other...
2  Hobby;Contribute to open-source projects;Other...
3                                                NaN
4                                                NaN

                                             EdLevel  \
0                          Primary/elementary school
1       Bachelor’s degree (B.A., B.S., B.Eng., etc.)
2    Master’s degree (M.A., M.S., M.Eng., MBA, etc.)
3  Some college/university study without earning ...
4  Secondary school (e.g. American high school, G...

                                           LearnCode  \
0                             Books / Physical media
1  Books / Physical media;Colleague;On the job tr...
2  Books / Physical media;Colleague;On the job tr...
3  Other online resources (e.g., videos, blogs, f...
4  Other online resources (e.g., videos, blogs, f...

                                     LearnCodeOnline  ... I prefer not to say  \
0                                                NaN  ...               False
1  Technical documentation;Blogs;Books;Written Tu...  ...               False
2  Technical documentation;Blogs;Books;Written Tu...  ...               False
3  Stack Overflow;How-to videos;Interactive tutorial  ...               False
4  Technical documentation;Blogs;Written Tutorial...  ...               False

  Independent contractor, freelancer, or self-employed  \
0                                              False
1                                              False
2                                              False
3                                              False
4                                              False

  Not employed, and not looking for work Not employed, but looking for work  \
0                                  False                              False
1                                  False                              False
2                                  False                              False
3                                  False                              False
4                                  False                              False

  Retired Student, full-time Student, part-time ConvertedCompYearly_MinMax  \
0   False              False              False                   0.003998
1   False              False              False                   0.003998
2   False              False              False                   0.003998
3   False               True              False                   0.003998
4   False               True              False                   0.003998

  ConvertedCompYearly_Log ExperienceLevel
0               11.082143             NaN
1               11.082143             Low
2               11.082143          Medium
3               11.082143             NaN
4               11.082143             NaN

[5 rows x 126 columns]
plt.bar(group_names, df_iefe.ExperienceLevel.value_counts())
plt.xlabel('Experience')
plt.ylabel('Count')
plt.title('Experience bins')
Text(0.5, 1.0, 'Experience bins')
Summary
In this lab, you:
-
Explored the dataset to identify inconsistencies and missing values.
-
Encoded categorical variables for analysis.
-
Handled missing values using imputation techniques.
-
Normalized and transformed numerical data to prepare it for analysis.
-
Engineered a new feature to enhance data interpretation.
Copyright © IBM Corporation. All rights reserved.