Bar Charts
Estimated time needed: 30 minutes
In this lab, you will focus on visualizing data.
The dataset will be provided to you in the form of an RDBMS.
You will use SQL queries to extract the necessary data.
Objectives
In this lab you will perform the following:
-
Visualize the distribution of data
-
Visualize the relationship between two features
-
Visualize the composition of data
-
Visualize comparison of data
Setup: Working with the Database
Install the needed libraries
!pip install pandas
Requirement already satisfied: pandas in /opt/conda/lib/python3.12/site-packages (3.0.0)
Requirement already satisfied: numpy>=1.26.0 in /opt/conda/lib/python3.12/site-packages (from pandas) (2.4.2)
Requirement already satisfied: python-dateutil>=2.8.2 in /opt/conda/lib/python3.12/site-packages (from pandas) (2.9.0.post0)
Requirement already satisfied: six>=1.5 in /opt/conda/lib/python3.12/site-packages (from python-dateutil>=2.8.2->pandas) (1.17.0)
!pip install matplotlib
!pip install seaborn
Requirement already satisfied: matplotlib in /opt/conda/lib/python3.12/site-packages (3.10.8)
Requirement already satisfied: contourpy>=1.0.1 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (1.3.3)
Requirement already satisfied: cycler>=0.10 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (0.12.1)
Requirement already satisfied: fonttools>=4.22.0 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (4.61.1)
Requirement already satisfied: kiwisolver>=1.3.1 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (1.4.9)
Requirement already satisfied: numpy>=1.23 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (2.4.2)
Requirement already satisfied: packaging>=20.0 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (24.2)
Requirement already satisfied: pillow>=8 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (12.1.1)
Requirement already satisfied: pyparsing>=3 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (3.3.2)
Requirement already satisfied: python-dateutil>=2.7 in /opt/conda/lib/python3.12/site-packages (from matplotlib) (2.9.0.post0)
Requirement already satisfied: six>=1.5 in /opt/conda/lib/python3.12/site-packages (from python-dateutil>=2.7->matplotlib) (1.17.0)
Requirement already satisfied: seaborn in /opt/conda/lib/python3.12/site-packages (0.13.2)
Requirement already satisfied: numpy!=1.24.0,>=1.20 in /opt/conda/lib/python3.12/site-packages (from seaborn) (2.4.2)
Requirement already satisfied: pandas>=1.2 in /opt/conda/lib/python3.12/site-packages (from seaborn) (3.0.0)
Requirement already satisfied: matplotlib!=3.6.1,>=3.4 in /opt/conda/lib/python3.12/site-packages (from seaborn) (3.10.8)
Requirement already satisfied: contourpy>=1.0.1 in /opt/conda/lib/python3.12/site-packages (from matplotlib!=3.6.1,>=3.4->seaborn) (1.3.3)
Requirement already satisfied: cycler>=0.10 in /opt/conda/lib/python3.12/site-packages (from matplotlib!=3.6.1,>=3.4->seaborn) (0.12.1)
Requirement already satisfied: fonttools>=4.22.0 in /opt/conda/lib/python3.12/site-packages (from matplotlib!=3.6.1,>=3.4->seaborn) (4.61.1)
Requirement already satisfied: kiwisolver>=1.3.1 in /opt/conda/lib/python3.12/site-packages (from matplotlib!=3.6.1,>=3.4->seaborn) (1.4.9)
Requirement already satisfied: packaging>=20.0 in /opt/conda/lib/python3.12/site-packages (from matplotlib!=3.6.1,>=3.4->seaborn) (24.2)
Requirement already satisfied: pillow>=8 in /opt/conda/lib/python3.12/site-packages (from matplotlib!=3.6.1,>=3.4->seaborn) (12.1.1)
Requirement already satisfied: pyparsing>=3 in /opt/conda/lib/python3.12/site-packages (from matplotlib!=3.6.1,>=3.4->seaborn) (3.3.2)
Requirement already satisfied: python-dateutil>=2.7 in /opt/conda/lib/python3.12/site-packages (from matplotlib!=3.6.1,>=3.4->seaborn) (2.9.0.post0)
Requirement already satisfied: six>=1.5 in /opt/conda/lib/python3.12/site-packages (from python-dateutil>=2.7->matplotlib!=3.6.1,>=3.4->seaborn) (1.17.0)
Download and connect to the database file containing survey data.
To start, download and load the dataset into a pandas DataFrame.
# Step 1: Download the dataset
!wget -O survey-data.csv https://cf-courses-data.s3.us.cloud-object-storage.appdomain.cloud/n01PQ9pSmiRX6520flujwQ/survey-data.csv

# Step 2: Import necessary libraries and load the dataset
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns
import textwrap
import numpy as np

# Load the data
df = pd.read_csv("survey-data.csv")

# Display the first few rows to understand the structure of the data
print(df.head())
print('Initial dataframe:', df.shape)
--2026-02-12 09:56:40--  https://cf-courses-data.s3.us.cloud-object-storage.appdomain.cloud/n01PQ9pSmiRX6520flujwQ/survey-data.csv
Resolving cf-courses-data.s3.us.cloud-object-storage.appdomain.cloud (cf-courses-data.s3.us.cloud-object-storage.appdomain.cloud)... 169.63.118.104
Connecting to cf-courses-data.s3.us.cloud-object-storage.appdomain.cloud (cf-courses-data.s3.us.cloud-object-storage.appdomain.cloud)|169.63.118.104|:443... connected.
HTTP request sent, awaiting response... 200 OK
Length: 159525875 (152M) [text/csv]
Saving to: ‘survey-data.csv’

survey-data.csv     100%[===================>] 152.13M  26.2MB/s    in 5.7s

2026-02-12 09:56:46 (26.7 MB/s) - ‘survey-data.csv’ saved [159525875/159525875]

   ResponseId                      MainBranch                 Age  \
0           1  I am a developer by profession  Under 18 years old
1           2  I am a developer by profession     35-44 years old
2           3  I am a developer by profession     45-54 years old
3           4           I am learning to code     18-24 years old
4           5  I am a developer by profession     18-24 years old

            Employment RemoteWork   Check  \
0  Employed, full-time     Remote  Apples
1  Employed, full-time     Remote  Apples
2  Employed, full-time     Remote  Apples
3   Student, full-time        NaN  Apples
4   Student, full-time        NaN  Apples

                                    CodingActivities  \
0                                              Hobby
1  Hobby;Contribute to open-source projects;Other...
2  Hobby;Contribute to open-source projects;Other...
3                                                NaN
4                                                NaN

                                             EdLevel  \
0                          Primary/elementary school
1       Bachelor’s degree (B.A., B.S., B.Eng., etc.)
2    Master’s degree (M.A., M.S., M.Eng., MBA, etc.)
3  Some college/university study without earning ...
4  Secondary school (e.g. American high school, G...

                                           LearnCode  \
0                             Books / Physical media
1  Books / Physical media;Colleague;On the job tr...
2  Books / Physical media;Colleague;On the job tr...
3  Other online resources (e.g., videos, blogs, f...
4  Other online resources (e.g., videos, blogs, f...

                                     LearnCodeOnline  ... JobSatPoints_6  \
0                                                NaN  ...            NaN
1  Technical documentation;Blogs;Books;Written Tu...  ...            0.0
2  Technical documentation;Blogs;Books;Written Tu...  ...            NaN
3  Stack Overflow;How-to videos;Interactive tutorial  ...            NaN
4  Technical documentation;Blogs;Written Tutorial...  ...            NaN

  JobSatPoints_7 JobSatPoints_8 JobSatPoints_9 JobSatPoints_10  \
0            NaN            NaN            NaN             NaN
1            0.0            0.0            0.0             0.0
2            NaN            NaN            NaN             NaN
3            NaN            NaN            NaN             NaN
4            NaN            NaN            NaN             NaN

  JobSatPoints_11           SurveyLength SurveyEase ConvertedCompYearly JobSat
0             NaN                    NaN        NaN                 NaN    NaN
1             0.0                    NaN        NaN                 NaN    NaN
2             NaN  Appropriate in length       Easy                 NaN    NaN
3             NaN               Too long       Easy                 NaN    NaN
4             NaN              Too short       Easy                 NaN    NaN

[5 rows x 114 columns]
Initial dataframe: (65437, 114)
Task 1: Visualizing Data Distributions
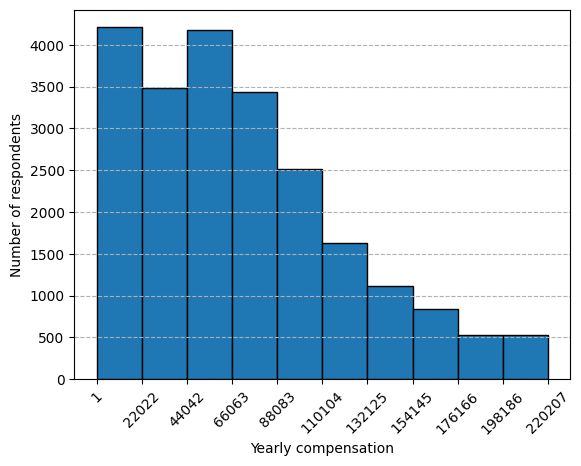
1. Histogram of ConvertedCompYearly
Visualize the distribution of yearly compensation (ConvertedCompYearly) using a histogram.
## Write your code here
comp = df.ConvertedCompYearly
q1, q3 = comp.quantile(.25), comp.quantile(.75)
iqr = q3 - q1
outliers1 = comp[(ch > q3 + 1.5 * iqr) | (comp < q1 - 1.5 * iqr)].sort_values(ascending=False)
comp_o = df[~df["ConvertedCompYearly"].isin(outliers1)]

ch_o = comp_o.ConvertedCompYearly.dropna()
count, bin_edges = np.histogram(ch_o)
ch_o.hist(edgecolor='black')
plt.xticks(bin_edges.round(decimals=0))
plt.xlabel('Yearly compensation')
plt.xticks(rotation=45)
plt.grid(False)
plt.grid(True, axis='y', linestyle='dashed')
plt.ylabel('Number of respondents')
plt.show()
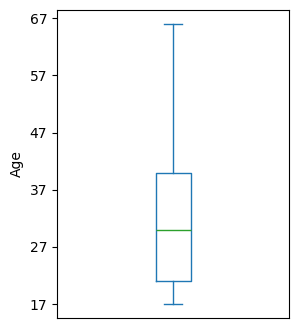
2. Box Plot of Age
Since Age is categorical in the dataset, convert it to numerical values for a box plot.
## Write your code here
comp_o["Age_numeric"] = df.Age.map({'Under 18 years old': 17, '18-24 years old': 21,
        'Prefer not to say': float('nan'), '25-34 years old': 30, '35-44 years old': 40,
        '45-54 years old': 50, '55-64 years old': 60, '65 years or older': 66})

comp_o.Age_numeric.plot(kind='box', figsize=(3, 4))
plt.ylabel('Age')
plt.yticks(range(17, 68, 10))
plt.xticks([])
plt.show()
Task 2: Visualizing Relationships in Data
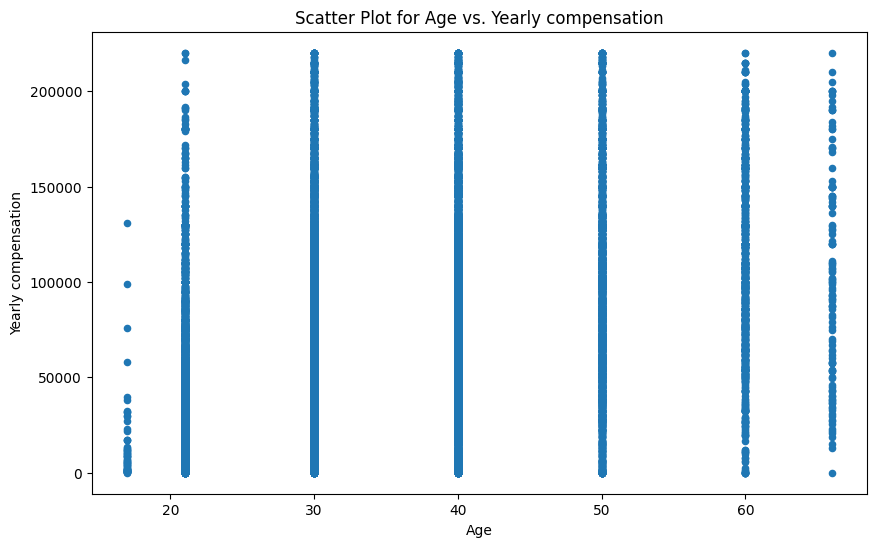
1. Scatter Plot of Age_numeric and ConvertedCompYearly
Explore the relationship between age and compensation.
## Write your code here
comp_o.plot(kind='scatter', x="Age_numeric", y="ConvertedCompYearly", figsize=(10, 6))

plt.title("Scatter Plot for Age vs. Yearly compensation")
plt.xlabel("Age")
plt.ylabel("Yearly compensation")

plt.show()
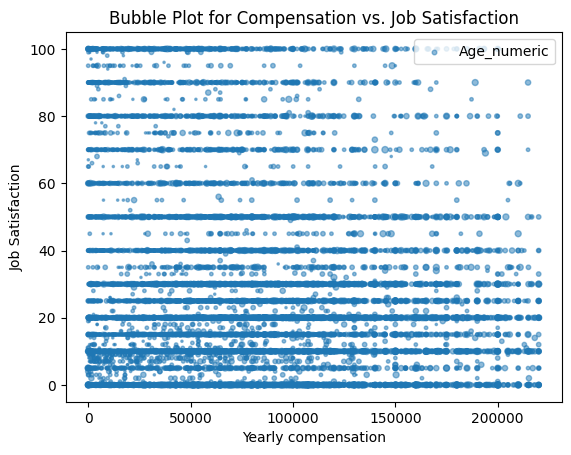
2. Bubble Plot of ConvertedCompYearly and JobSatPoints_6 with Age_numeric as Bubble Size
Explore how compensation and job satisfaction are related, with age as the bubble size.
## Write your code here
norm_age = ((comp_o.Age_numeric - comp_o.Age_numeric.min()) /
            (comp_o.Age_numeric.max() - comp_o.Age_numeric.min()))
ax = comp_o.plot(kind='scatter',
            x='ConvertedCompYearly',
            y='JobSatPoints_6',
            alpha=0.5,
            s=norm_age * 20 + 1)

ax.set_ylabel('Job Satisfaction')
ax.set_xlabel('Yearly compensation')
ax.legend(['Age_numeric'], loc='upper right')
ax.set_title('Bubble Plot for Compensation vs. Job Satisfaction')
Text(0.5, 1.0, 'Bubble Plot for Compensation vs. Job Satisfaction')
Task 3: Visualizing Composition of Data with Bar Charts
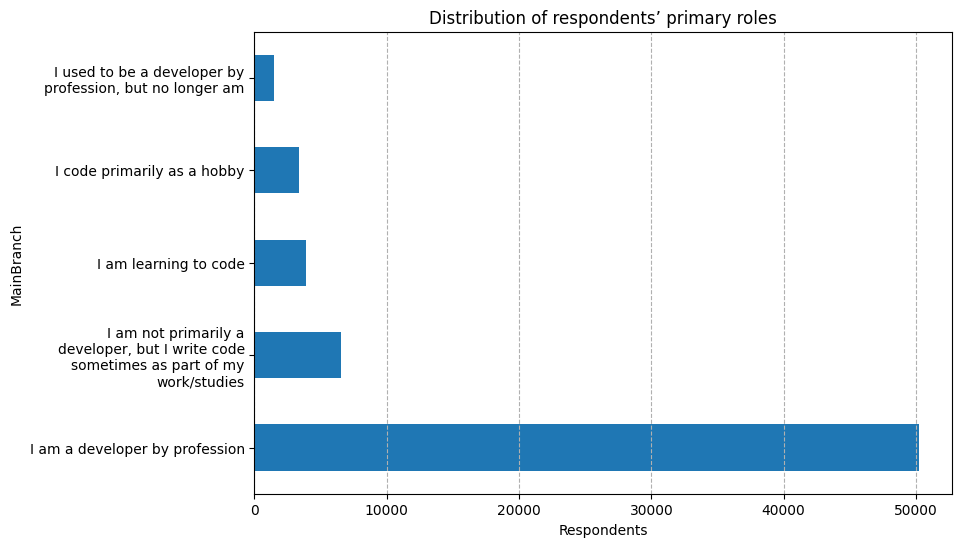
1. Horizontal Bar Chart of MainBranch Distribution
Visualize the distribution of respondents’ primary roles to understand their professional focus.
## Write your code here
ax = df['MainBranch'].value_counts().plot(kind='barh', figsize=(9, 6))

ylabels = [textwrap.fill(label.get_text(), width=30) for label in ax.get_yticklabels()]
ax.set(xlabel='Respondents', ylabel='MainBranch')
ax.set_yticklabels(ylabels)
plt.title('Distribution of respondents’ primary roles')
plt.xticks(rotation=0)
plt.grid(True, axis='x', linestyle='dashed')

plt.show()
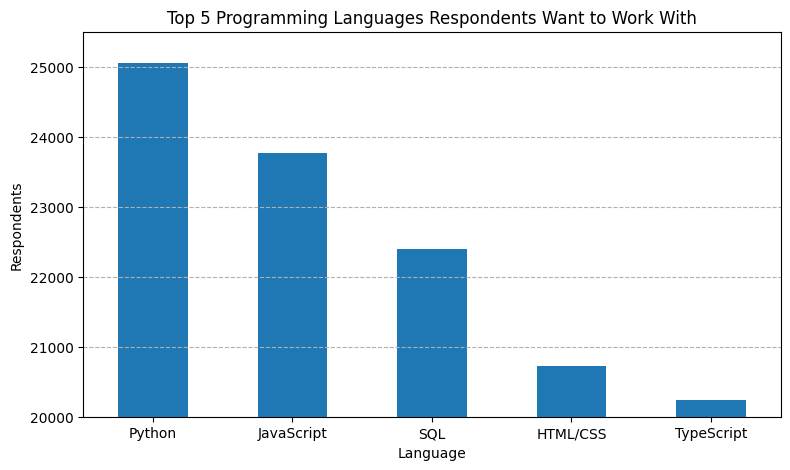
2. Vertical Bar Chart of Top 5 Programming Languages Respondents Want to Work With
Identify the most desired programming languages based on LanguageWantToWorkWith.
## Write your code here
dummies = df['LanguageWantToWorkWith'].str.get_dummies(sep=';')
# Count total occurrences and sort
counts = dummies.sum().sort_values(ascending=False)
top5lang = counts.iloc[:5]
#top5lang.info()
ax = top5lang.plot(kind='bar', figsize=(9, 5))

ax.set(xlabel='Language', ylabel='Respondents')
plt.title('Top 5 Programming Languages Respondents Want to Work With')
plt.xticks(rotation=0)
plt.grid(True, axis='y', linestyle='dashed')
plt.ylim(20000, 25500)
plt.show()
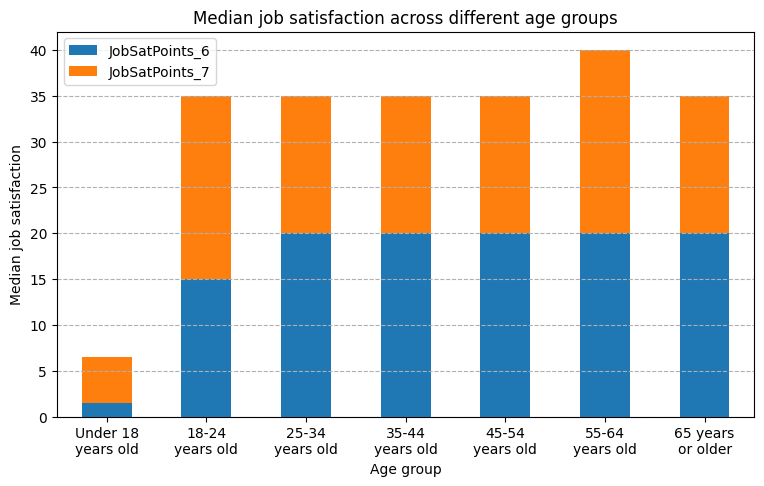
3. Stacked Bar Chart of Median JobSatPoints_6 and JobSatPoints_7 by Age Group
Compare job satisfaction metrics across different age groups with a stacked bar chart.
## Write your code here
sa = df[["JobSatPoints_6", "JobSatPoints_7", "Age"]].groupby('Age', as_index=False).median()
order = [7, 0, 1, 2, 3, 4, 5]
sa = sa.reindex(order)

ax = sa.plot(kind='bar', x='Age', figsize=(9, 5), stacked=True)

xlabels = [textwrap.fill(label.get_text(), width=10) for label in ax.get_xticklabels()]
ax.set(xlabel='Age group', ylabel='Median job satisfaction')
ax.set_xticklabels(xlabels)
plt.title('Median job satisfaction across different age groups')
plt.xticks(rotation=0)
plt.grid(True, axis='y', linestyle='dashed')

plt.show()
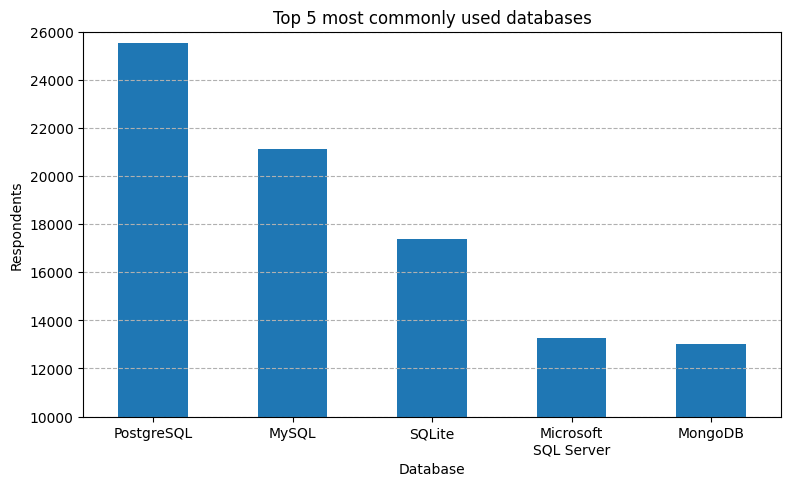
4. Bar Chart of Database Popularity (DatabaseHaveWorkedWith)
Identify the most commonly used databases among respondents by visualizing DatabaseHaveWorkedWith.
## Write your code here
dummies = df['DatabaseHaveWorkedWith'].str.get_dummies(sep=';')
# Count total occurrences and sort
counts = dummies.sum().sort_values(ascending=False)
top5datab = counts.iloc[:5]
ax = top5datab.plot(kind='bar', figsize=(9, 5))

xlabels = [textwrap.fill(label.get_text(), width=10) for label in ax.get_xticklabels()]
ax.set(xlabel='Database', ylabel='Respondents')
ax.set_xticklabels(xlabels)
plt.title('Top 5 most commonly used databases')
plt.xticks(rotation=0)
plt.grid(True, axis='y', linestyle='dashed')
plt.ylim(10000, 26000)
plt.show()
Task 4: Visualizing Comparison of Data with Bar Charts
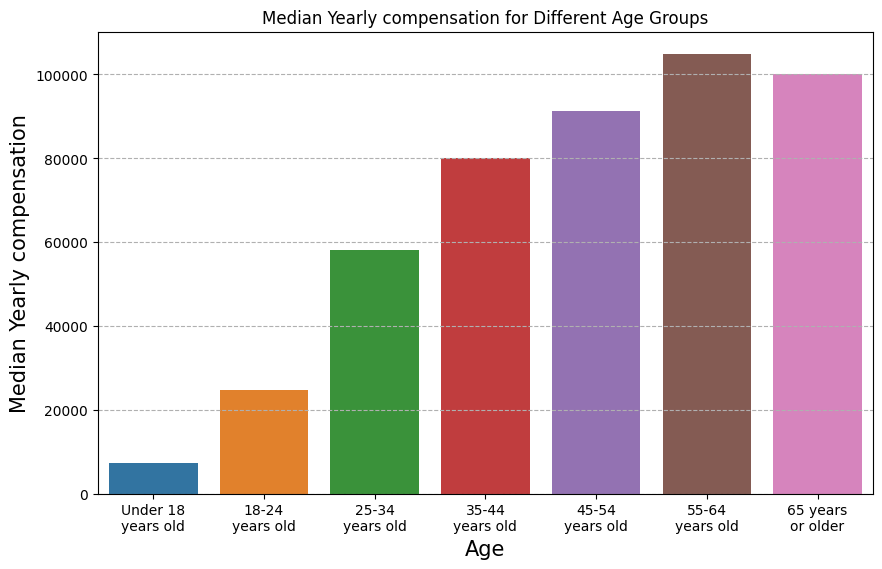
1. Grouped Bar Chart of Median ConvertedCompYearly for Different Age Groups
Compare median compensation across multiple age groups with a grouped bar chart.
## Write your code here comp_o
cag = comp_o.groupby(['Age'], as_index=False)['ConvertedCompYearly'].median()
order = [7, 0, 1, 2, 3, 4, 5]
cag = cag.reindex(order)

plt.figure(figsize=(10, 6))
ax = sns.barplot(data=cag, x='Age', y='ConvertedCompYearly', hue='Age')
ax.set(title='Median Yearly compensation for Different Age Groups')
xlabels = [textwrap.fill(label.get_text(), width=10) for label in ax.get_xticklabels()]
ax.set_xticklabels(xlabels)
ax.set_xlabel('Age', fontsize=15)
ax.set_ylabel('Median Yearly compensation', fontsize=15)
plt.grid(True, axis='y', linestyle='dashed')
plt.show()
/tmp/ipykernel_1600/4215599356.py:10: UserWarning: set_ticklabels() should only be used with a fixed number of ticks, i.e. after set_ticks() or using a FixedLocator.
  ax.set_xticklabels(xlabels)
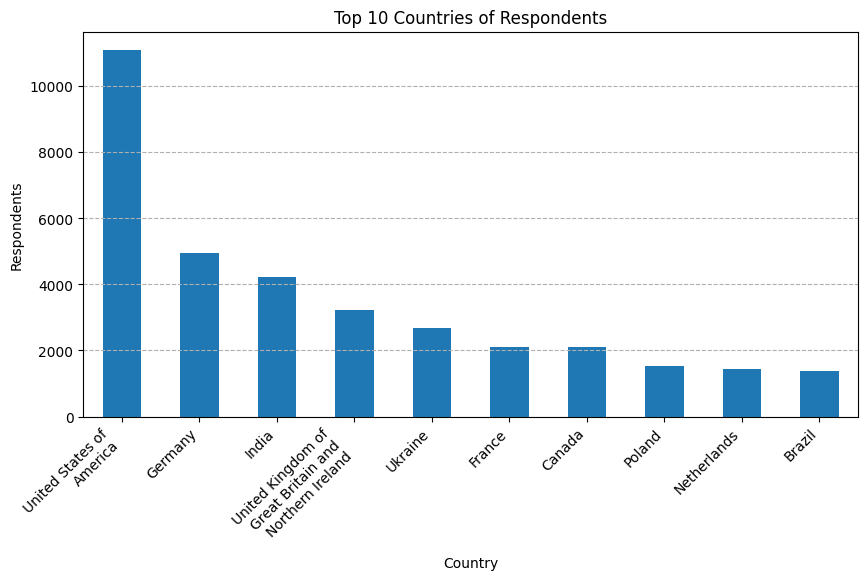
2. Bar Chart of Respondent Count by Country
Show the distribution of respondents by country to see which regions are most represented.
## Write your code here
topcountry = df.Country.value_counts().iloc[:10]
ax = topcountry.plot(kind='bar', figsize=(10, 5))

xlabels = [textwrap.fill(label.get_text(), width=20) for label in ax.get_xticklabels()]
ax.set_xticklabels(xlabels)
ax.set(xlabel='Country', ylabel='Respondents')
plt.title('Top 10 Countries of Respondents')
plt.xticks(rotation=45, ha="right")
plt.grid(True, axis='y', linestyle='dashed')
plt.show()
Final Step: Review
This lab demonstrates how to create and interpret different types of bar charts, allowing you to analyze the composition, comparison, and distribution of categorical data in the Stack Overflow dataset, including main professional branches, programming language preferences, and compensation by age group. Bar charts effectively compare counts and median values across various categories.
Summary
After completing this lab, you will be able to:
- Create a horizontal bar chart to visualize the distribution of respondents' primary roles, helping to understand their professional focus.
- Develop a vertical bar chart to identify the most desired programming languages based on the LanguageWantToWorkWith variable.
- Use a stacked bar chart to compare job satisfaction metrics across different age groups.
- Create a bar chart to visualize the most commonly used databases among respondents using the DatabaseHaveWorkedWith variable.
Authors:
Ayushi Jain
Other Contributors:
- Rav Ahuja
- Lakshmi Holla
- Malika
Copyright © IBM Corporation. All rights reserved.